
DOC OPS.
An AI document assistant: an invoice, price list or supplier scan becomes a verified table. OCR, schema-based extraction, arithmetic, VAT, duplicates and export — with a human in the loop.
Role
Product, backend, UI, deploy
Year
2026
Status
Live demo · 2026
Public demo on synthetic documents. Uploaded files are deleted after 24 hours; no real client data is used.
44
documents in the benchmark
99.6%
field accuracy
97.7%
documents fully correct
5.8s
median per document
The error is visible before it reaches accounting
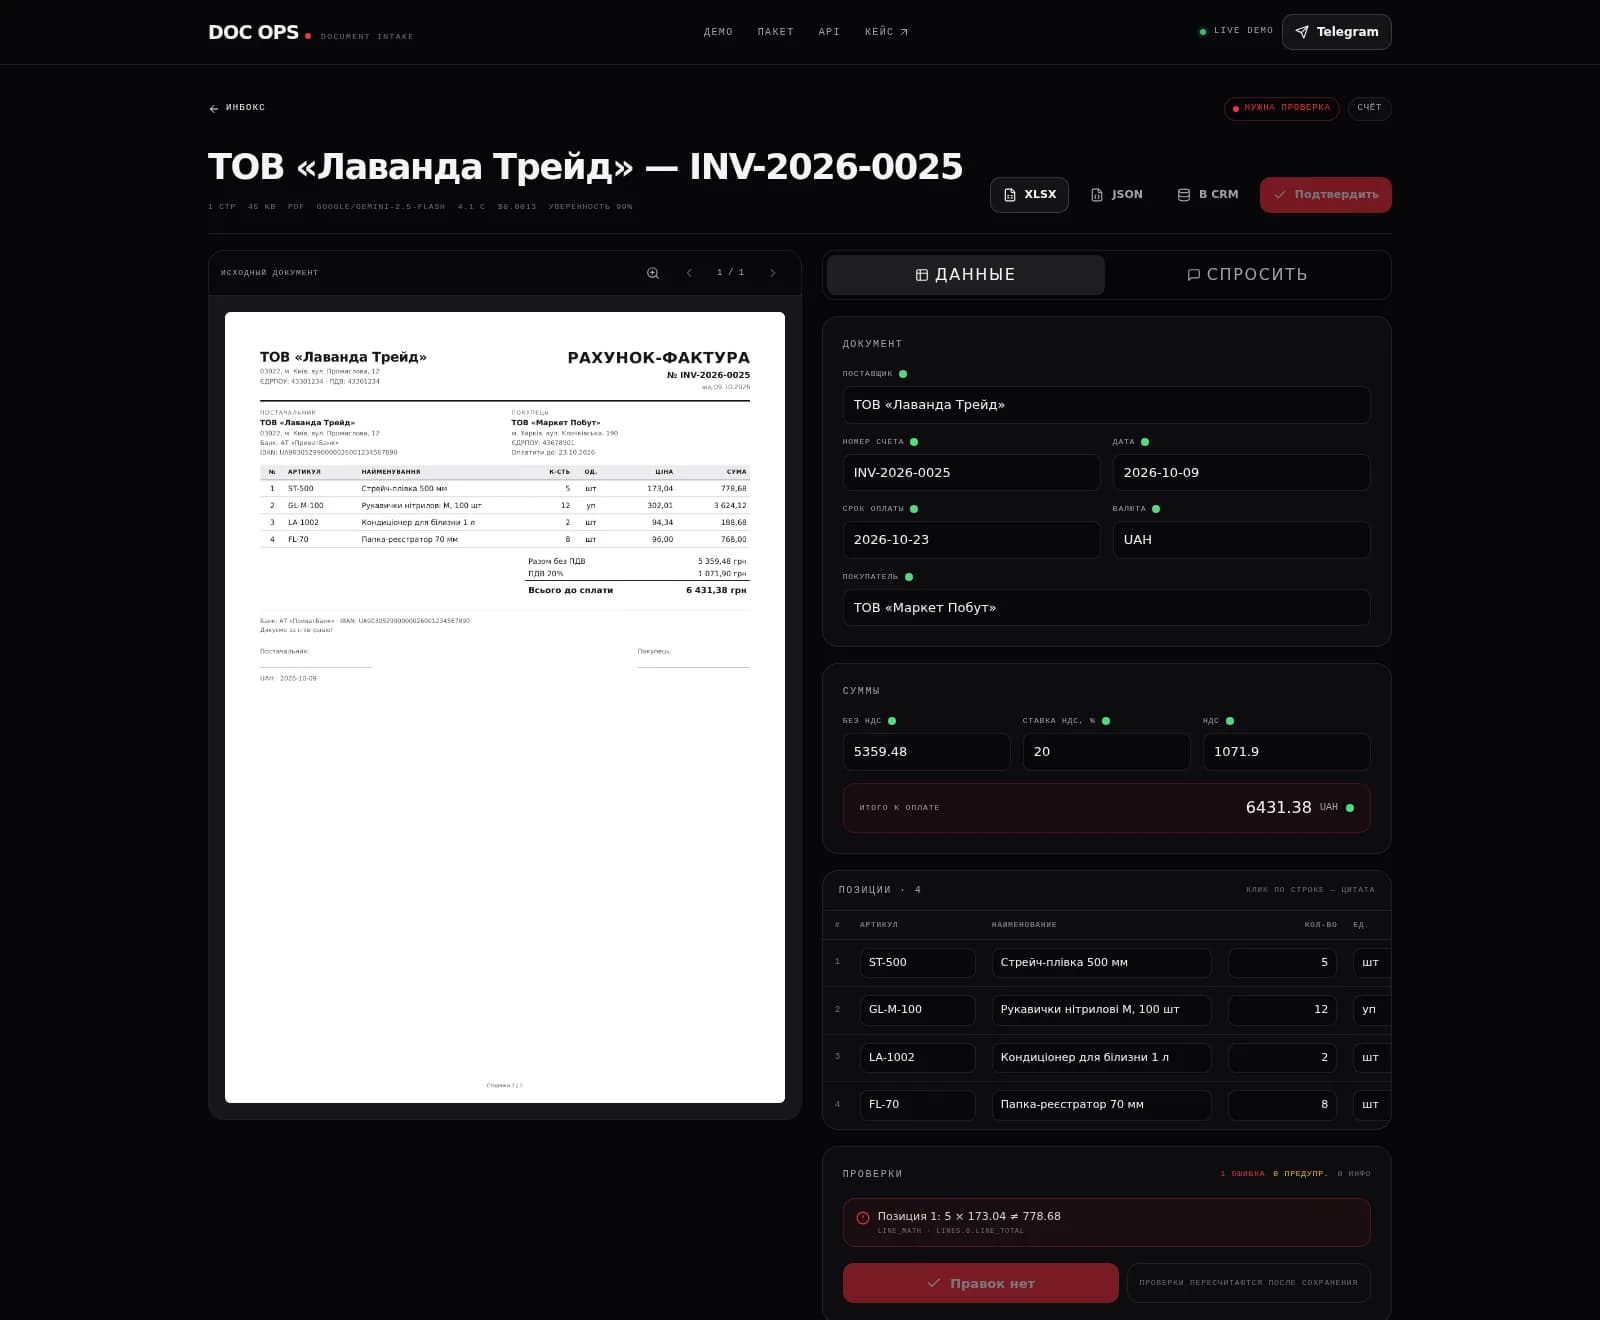
The model extracts data, but it does not decide whether the data can be trusted. A separate deterministic layer checks arithmetic, VAT, dates and duplicates. On the demo set it caught all three deliberately broken cases.
3/3
edge cases caught
0.2s
XLSX without a model
24h
file lifetime
Task
A wholesale team receives dozens of invoices and price lists as PDFs, scans and Excel files. Line items are retyped by hand: 3–5 minutes per document, arithmetic errors, duplicate uploads and no audit trail. A generic “chat with your PDF” does not help: the team needs rows in a table, not answers.
Solution
A document intake pipeline: file → text or OCR → type → extraction against a strict JSON schema → validation → review screen → XLSX / JSON / CRM. The model fills fields, a human confirms ambiguous ones, and a deterministic layer catches arithmetic and duplicates.
Five steps, one result
Every step can be inspected separately: text, type, fields, checks, human decision.
Ingest
PDF, JPG/PNG, DOCX, XLSX. MIME and size checks, sha256, page previews, 20-page limit.
Text and OCR
Text layer via pdftotext; scans and photos via a vision model. XLSX is parsed deterministically, without an LLM.
Extraction
Type classification and schema JSON: supplier, number, dates, totals, every line. Zod plus one retry with the validation error.
Validation
Quantity × price, line sum, VAT, total, duplicate number, date range, required fields.
Review and export
Low-confidence and citation highlights, inline edits, confirmation, XLSX/CSV/JSON and a webhook.
const source = await readSource(doc);          // text | vision
const type = await classifyDocument(source);  // invoice | price_list
const result = await extractDocument(type, source); // JSON + Zod retry

const checks = validateExtraction(result.data, doc.id);
const status = checks.some((c) => c.severity === "error")
  ? "needs_review"
  : "done";

// arithmetic, VAT, dates, duplicate number —
// deterministic rules, not another model call
Stack
Extraction and validation are separate: the LLM does not decide whether arithmetic adds up. That makes errors explainable and reproducible.
Decisions
Schema-first, not free chat
The model fills a typed schema rather than answering in prose. The result can be validated, compared and exported.
Deterministic validation
Arithmetic, VAT, dates and duplicates are plain TypeScript. Explainable, reproducible and independent of model temperature.
Human-in-the-loop
Per-field confidence, blockers and warnings. Below the threshold a document cannot move on without human confirmation.
Excel without a model
XLSX price lists are parsed by code: headers, columns, numbers. 0.2 seconds and zero model cost per document.
Features
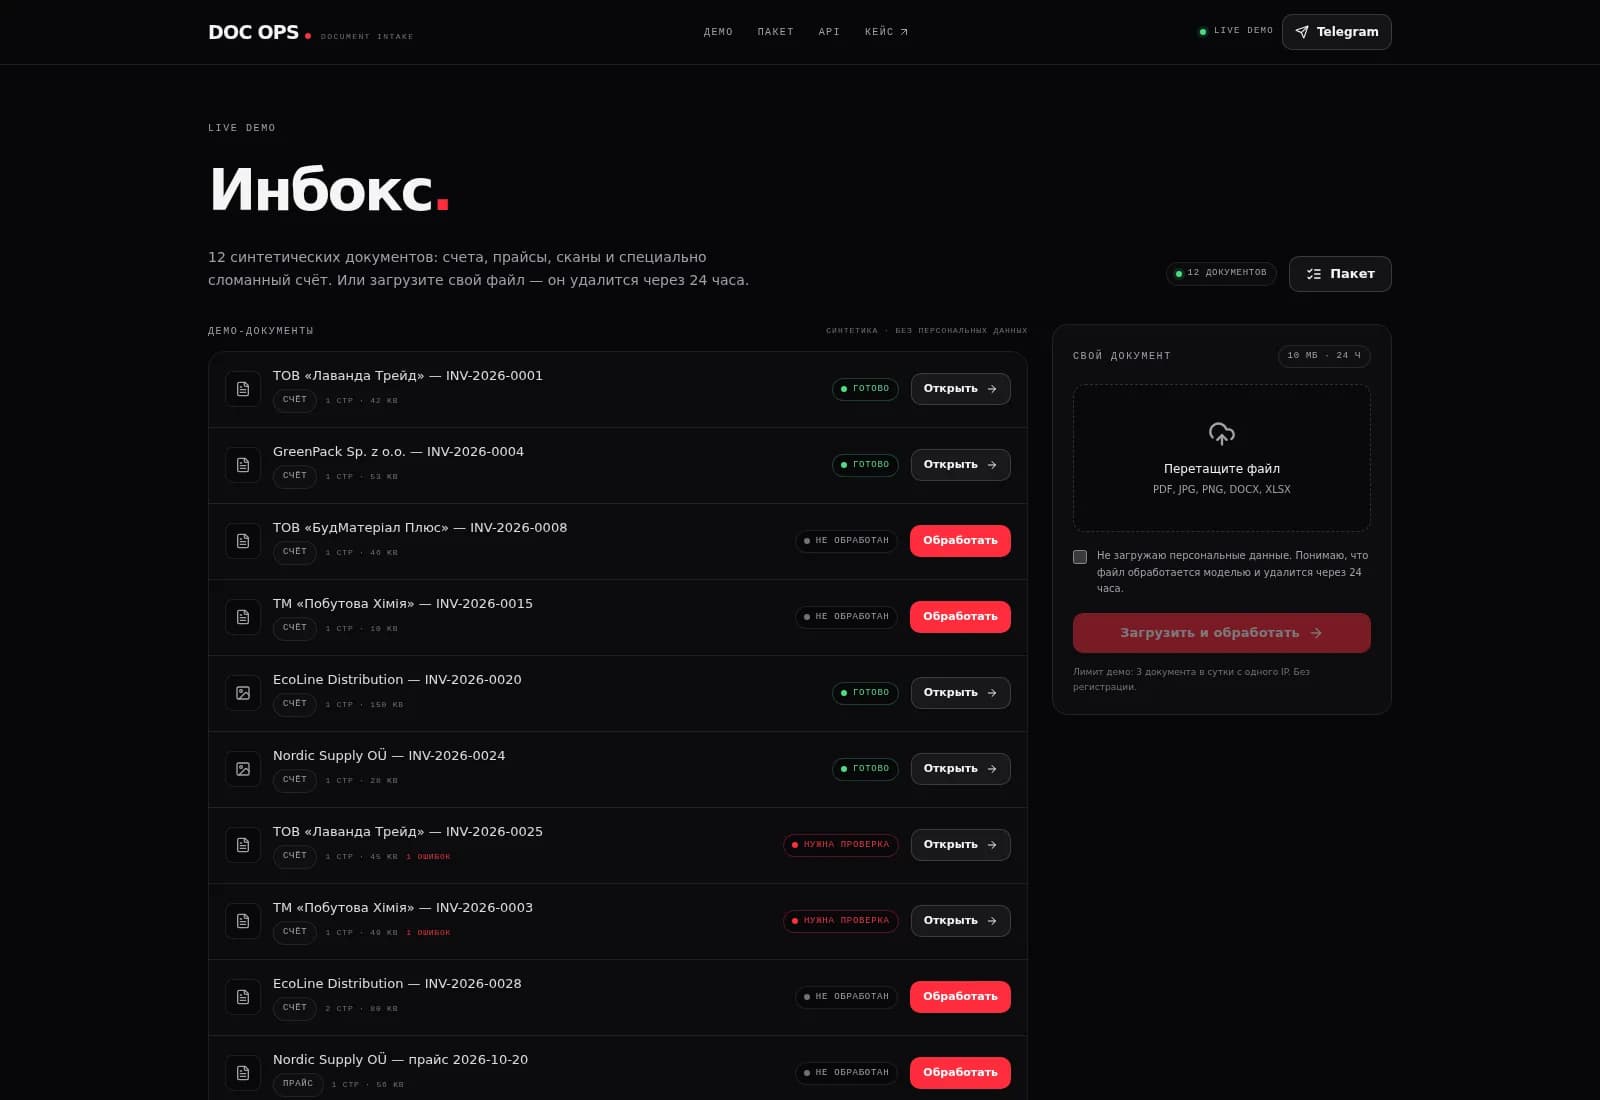
Invoices, price lists, scans, DOCX and XLSX
OCR and vision for photos
Line items, totals, VAT and currency
Arithmetic and duplicate checks
Confidence and page citations
Inline edits and confirmation
XLSX / CSV / JSON export
Public demo API
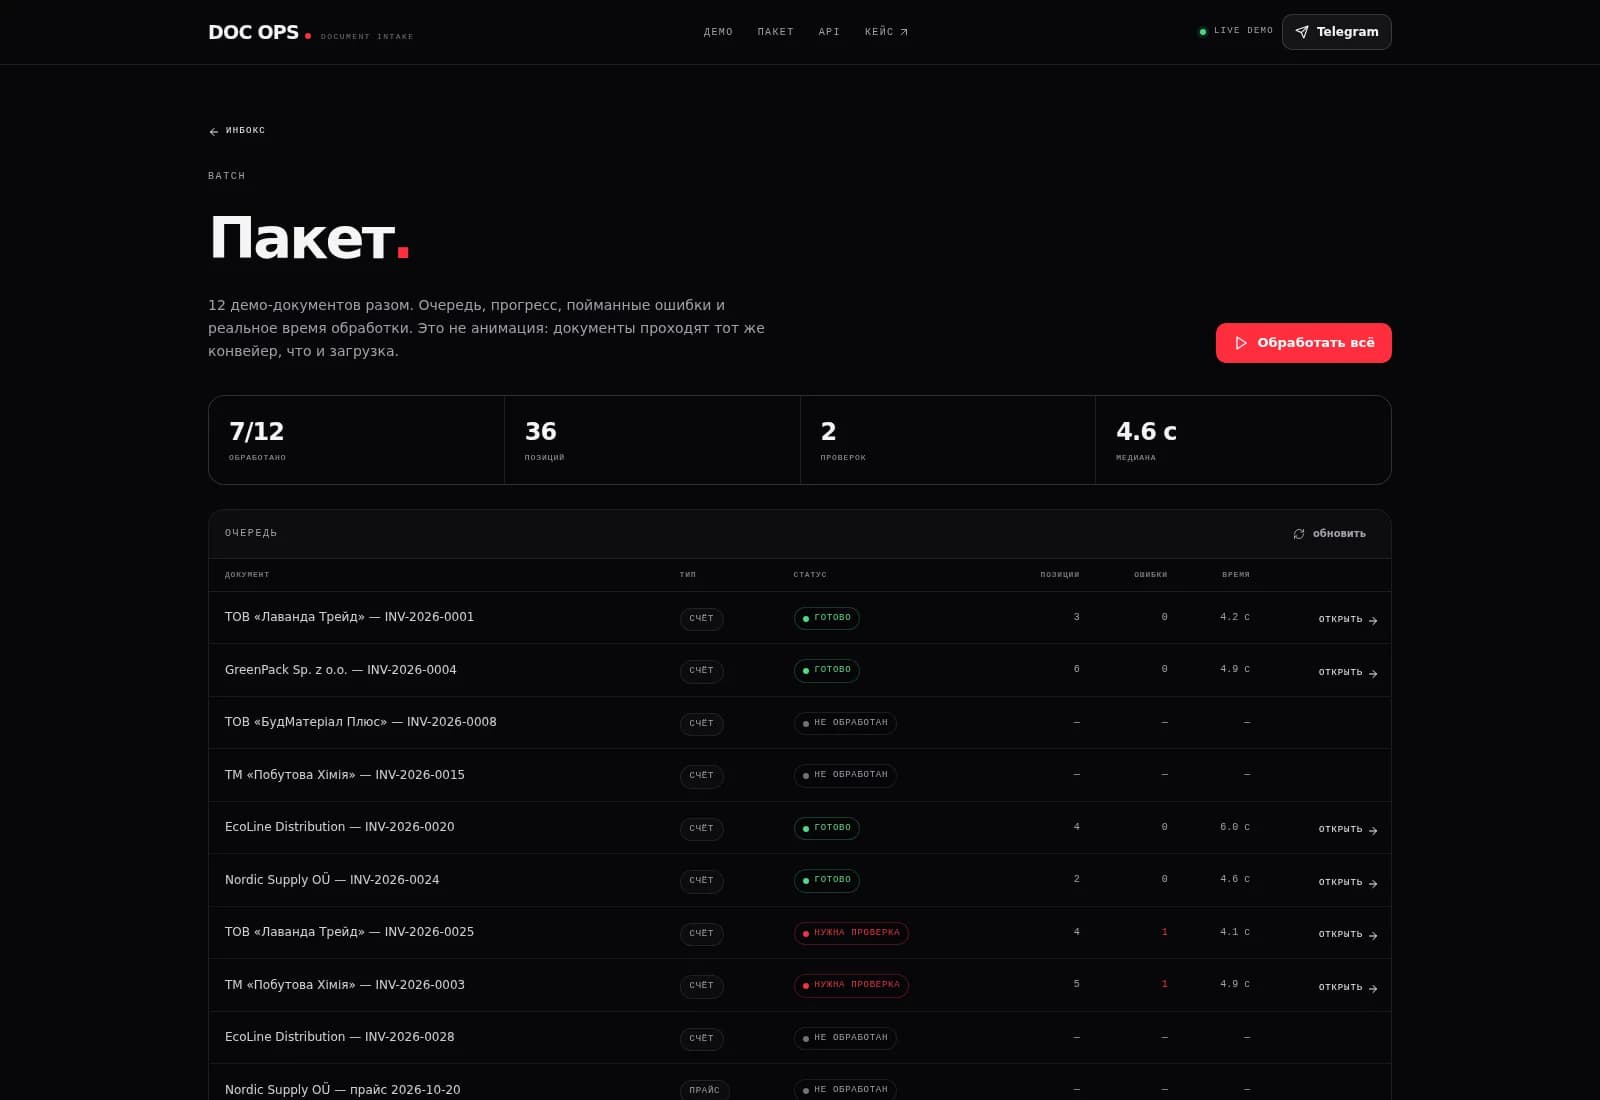
Batch processing
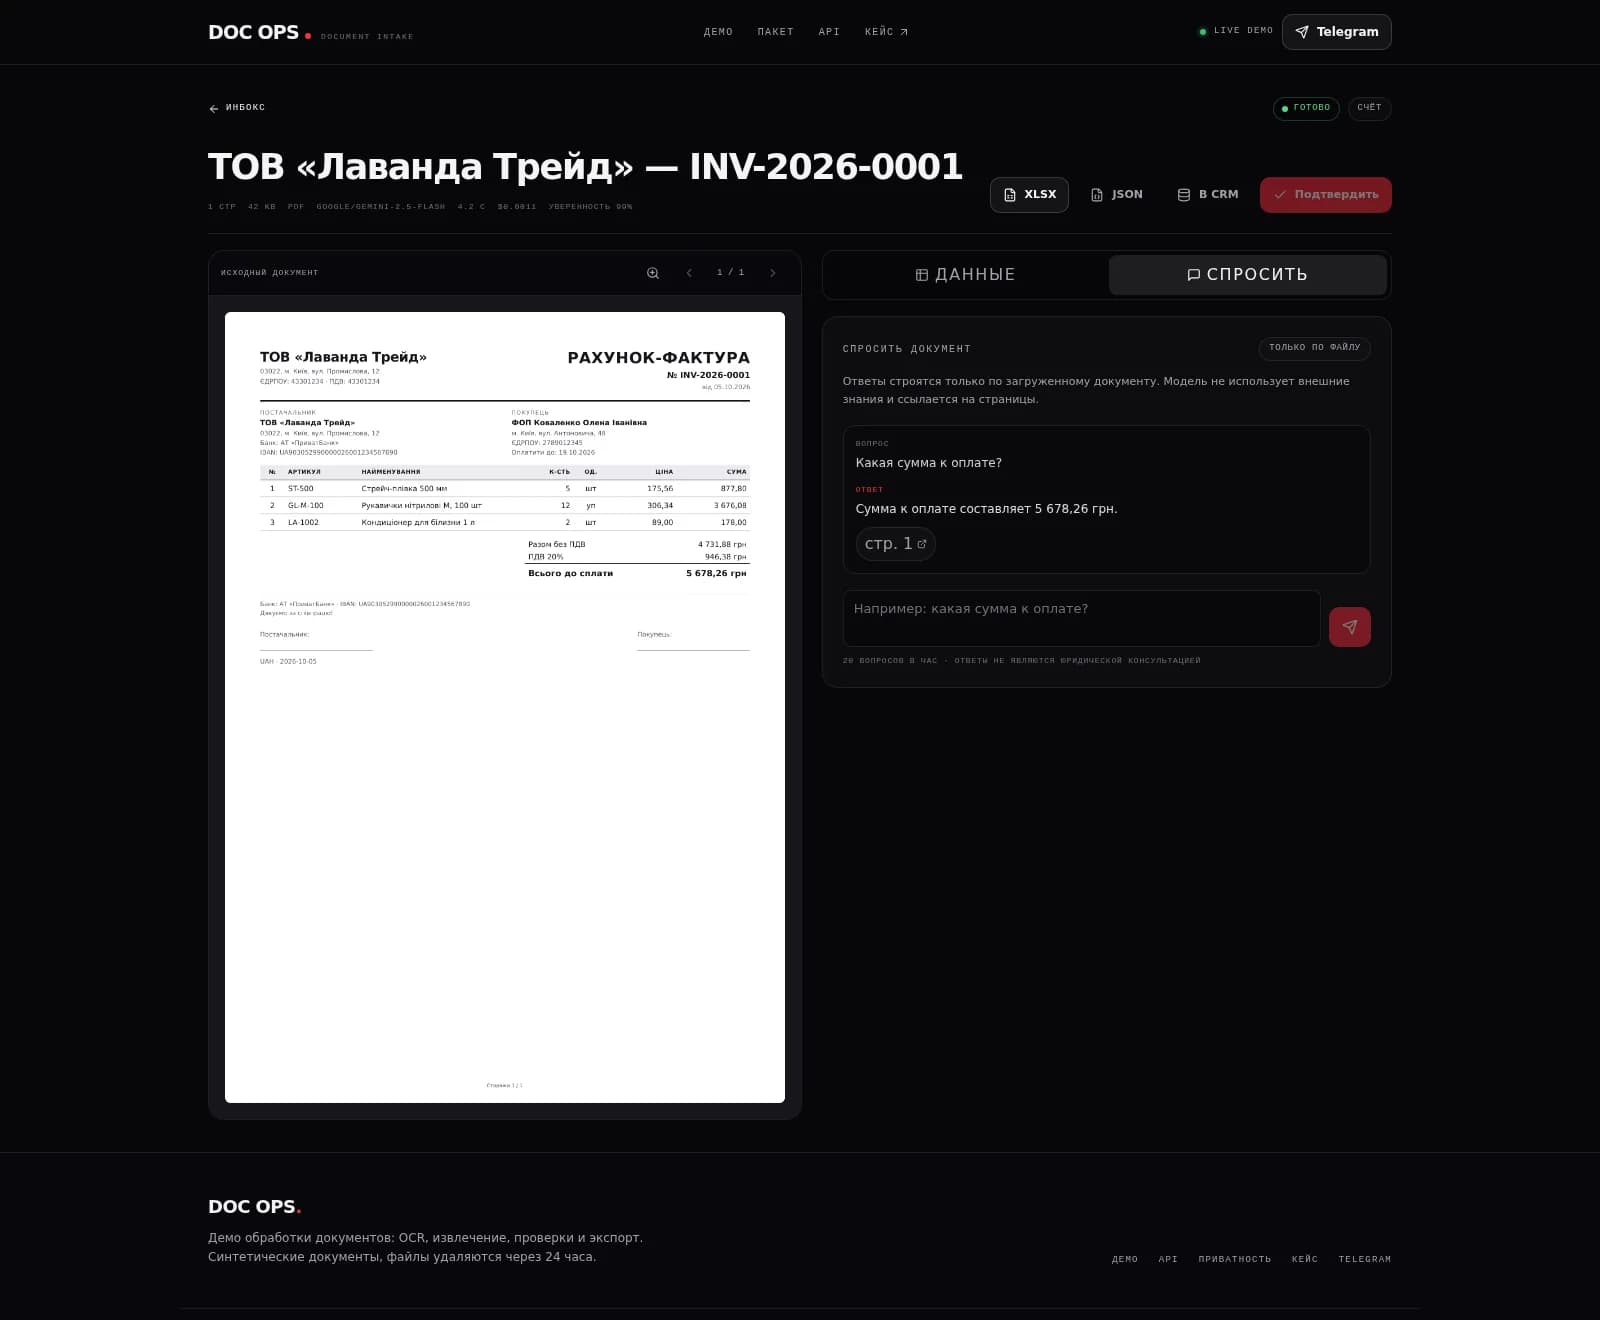
Questions about the document
3/day limits and 24h TTL
Documents in RU / EN / UK
Interface
Real demo screenshots: inbox, review, batch and document questions.
Benchmark
44 synthetic documents with ground truth: text PDFs, scans, DOCX, XLSX and deliberately broken invoices. The numbers are produced by a script, not by hand. Two runs: 43–44 of 44 documents fully correct.
99.6%
Field accuracy
100%
Line-item accuracy
43 / 44
Documents fully correct
5.8 s
Median per document
$0.0015
Estimated cost
3 / 3
Edge cases caught
Need document intake for your workflow?
I can show how to plug the pipeline into a CRM, 1C or n8n: from file intake to human review and export.